This product announcement is available in English.
Trio-Spark v1.4: one model for text and vision, same API
Spark makes one decision inside the bounds your application sets: two to eight choices in, one selected choice and a probability for every choice out, from a single forward pass. No text is generated, so there is no answer to parse.
v1.4 is now serving every Trio-Spark request. One model handles structured text, a single image or camera frame, and 2–4-frame sampled video. There is nothing to change on your side: request shape, price and limits are the same, and every existing model name is served by v1.4. New integrations can simply use trio-spark.
Thirteen benchmarks, five models
We ran Trio-Spark and four other fast decision models on the same items. Across a ten-task panel of 2,977 decisions, Trio-Spark answered 91.5% correctly, the best score of the five on 6 of 13 rows. The median model time per decision was 118 ms.
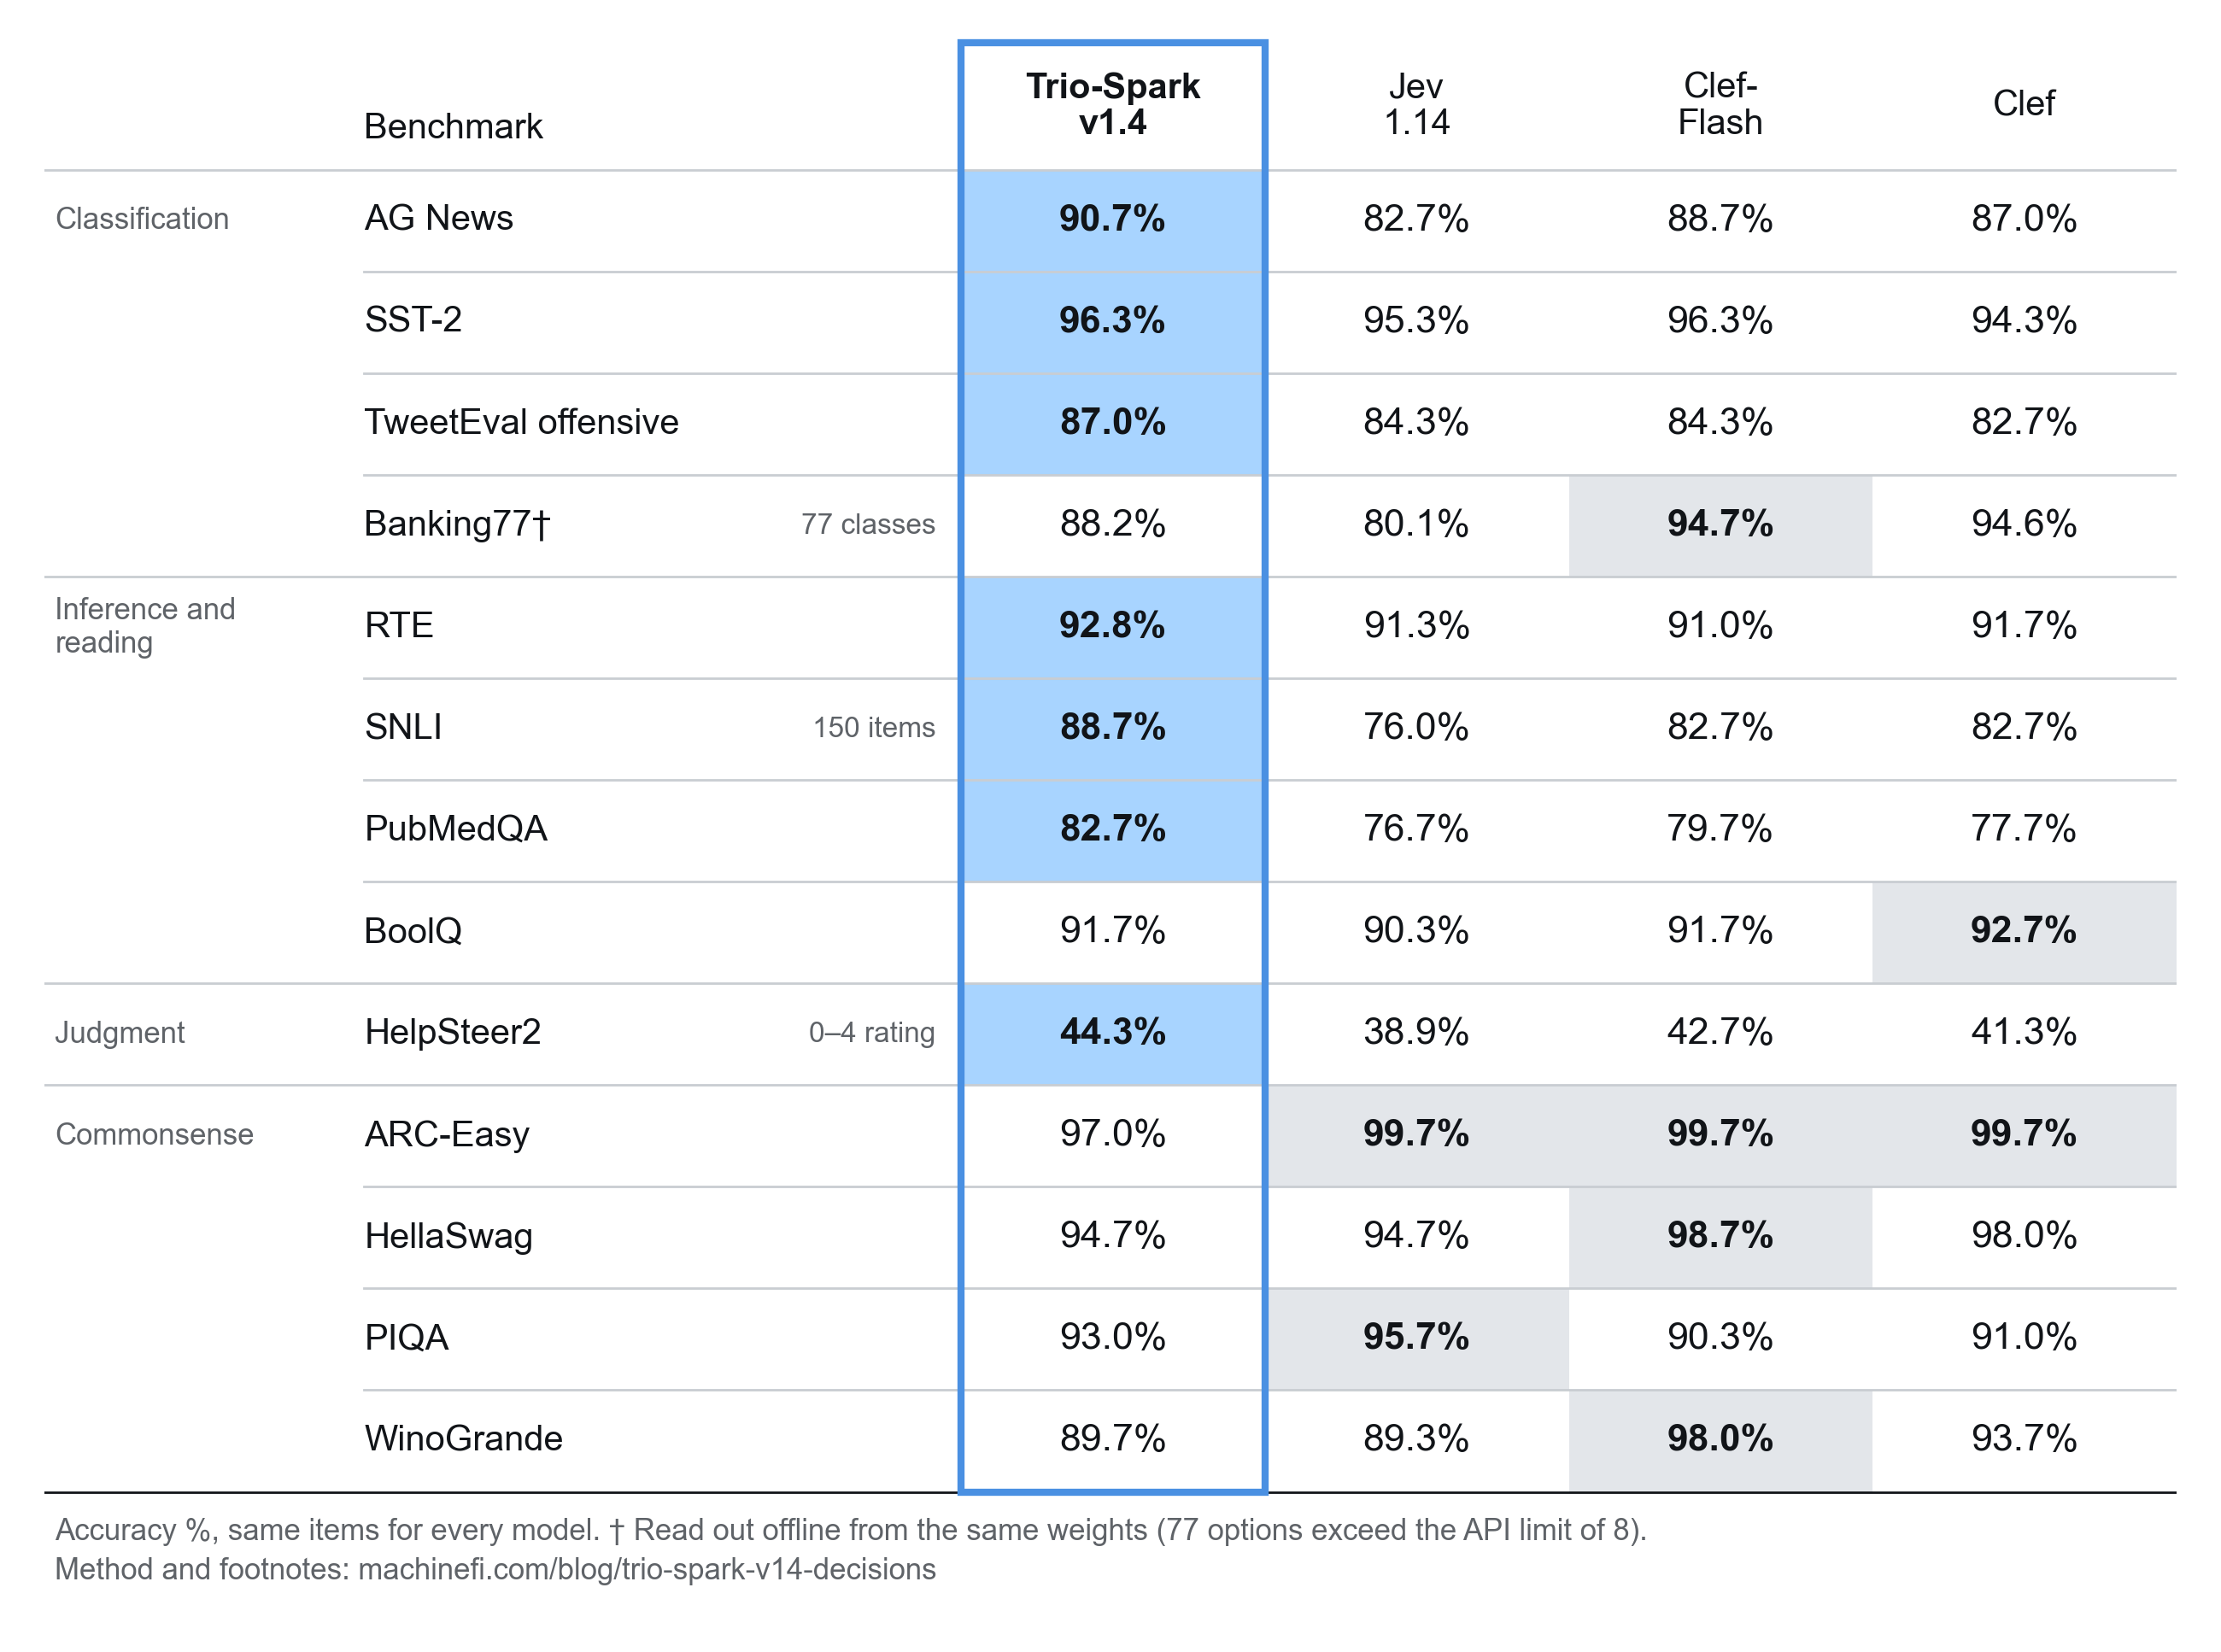
The picture is mixed, and we want to show it that way. Trio-Spark has the best score on PubMedQA, RTE, TweetEval offensive, SNLI and HelpSteer2, and ties Clef-Flash on SST-2. On the panel total it is ahead of Clef (90.8%) and Jev 1.14 (90.0%) and 0.3 points behind Clef-Flash (91.8%). Others lead elsewhere: Clef-Flash on HellaSwag, WinoGrande and Banking77; Jev on PIQA; Clef on BoolQ; Laya on AG News.
The full table
| Task | Trio-Spark | Jev 1.14 | Clef | Clef-Flash | Laya |
|---|---|---|---|---|---|
| AG News (300) | 90.7 | 82.7 | 87.0 | 88.7 | 91.7 |
| ARC-Easy (300) | 97.0 | 99.7 | 99.7 | 99.7 | 48.0 |
| BoolQ (300) | 91.7 | 90.3 | 92.7 | 91.7 | 80.7 |
| HellaSwag (300) | 94.7 | 94.7 | 98.0 | 98.7 | 28.3 |
| PIQA (300) | 93.0 | 95.7 | 91.0 | 90.3 | 53.7 |
| PubMedQA (300) | 82.7 | 76.7 | 77.7 | 79.7 | 57.0 |
| RTE (277) | 92.8 | 91.3 | 91.7 | 91.0 | 83.0 |
| SST-2 (300) | 96.3 | 95.3 | 94.3 | 96.3 | 91.0 |
| TweetEval offensive (300) | 87.0 | 84.3 | 82.7 | 84.3 | 78.3 |
| WinoGrande (300) | 89.7 | 89.3 | 93.7 | 98.0 | 50.3 |
| SNLI (150) | 88.7 | 76.0 | 82.7 | 82.7 | 46.0 |
| HelpSteer2 (0–4 score) (300) | 44.3 | 38.9 | 41.3 | 42.7 | 35.3 |
| Banking77 (77-way)† (300) | 88.2 | 80.1 | 94.6 | 94.7 | 38.7 |
| Ten-task total (2,977) | 91.5 | 90.0 | 90.8 | 91.8 | 66.1 |
How we measured
- Trio-Spark: the production API code path with the served weights, one request per item. Requests the API rejects (over 1,024 input tokens) count as wrong. Model time is measured around the model call and excludes network and platform overhead.
- Jev: official API, which returned
jev-1.14.0, October 28, 2026, no retries; four BoolQ requests that timed out count as wrong. Clef and Clef-Flash (Cloudflare Workers AI) and Laya (official SDK): recorded October 7–8, 2026. HelpSteer2 and Banking77 peer scores average five orderings of the options. - Banking77 has 77 options, more than the API’s limit of eight, so Spark’s Banking77 is read out offline from the same weights.
Where to be careful
Benchmarks are not your workload. On our internal GUI-action suite Trio-Spark is less reliable than on the tasks above, so if your agent drives a GUI, measure it on your own screens first. Use the probabilities to rank choices and to route uncertain cases to review, and set any automation threshold on your own data.
Same request
{
  "model": "trio-spark",
  "task": "The user asked to export the current report as CSV. Choose the next safe UI action from the available controls.",
  "state": {
    "app": "Reports",
    "screen": "Report details",
    "visible_controls": [
      "Export menu",
      "Filters",
      "Help"
    ]
  },
  "choices": [
    {
      "id": "open_export_menu",
      "description": "Open the Export menu"
    },
    {
      "id": "open_filters",
      "description": "Open report filters"
    },
    {
      "id": "wait",
      "description": "Wait for more information"
    }
  ]
}
Include a choice such as wait or ask for review when your application needs one. Images and sampled video use the same request with a media field; see the API docs.
A small decision, a small bill
Text and visual input stay at $0.042 per million billed input tokens. Output is free. New accounts get 100 free decisions. See pricing.
Give your agent a next move.
Bring a real state and the actions your application allows.
Try Trio-Spark Read the API docs